MongoDB change streams overview
Data Integration Log-Based extraction mode provides a real-time stream of any changes made to the databases and tables configured, eliminating the need to implement and maintain incremental fields or retrieve data via select queries. It also lets you retrieve schema changes from the database.
Working with change streams extraction
Data Integration uses the Change Data Capture architecture to continuously pull new rows from the Change Streams to retrieve data.
Change Streams is a fast and effective method of continuously fetching data from databases using the database transaction log.
Data Integration uses the Overwrite loading mode to take a full snapshot (or migration) of the tables you select to align the data and metadata as it was on the first run. Data Integration takes the existing Change Stream records and performs an Upsert-Merge to the target table(s) after the migration is complete, while continuing to fetch new records from the log as the source creates them.
Data Integration MongoDB connection reads the Change Stream records and generates change events in the FileZone files for row-level INSERT and UPDATE commands. Each file represents a set of database actions that occur over a period of time. The data from the log is continuously streamed into the FileZone path established in the Data Flow and pushed into the target by the Data Flow's scheduled frequency. This method saves the data first in the FileZone, and then it may be pushed into the target DWH at any moment.
The Target topic covers FileZone in further detail.
For further information about Change Streams Metadata Fields, refer to our Database Overview document.
CDC point in time position feature
The CDC Point in Time Position feature allows users to gain deeper insights into the operational details of a Data Flow's streaming process. This feature is essential for data recovery and synchronization, enabling users to locate and retrieve data from a specific point in history using the exact information stored in the CDC log position. For additional information, refer to our CDC Point in Time position.
Load tables with log-snapshot tables
Loading your data from a database to a target using CDC has an additional capability of pulling the log snapshot table.
To configure this, open the Data Flow and go to the Schema tab. Under Multi Tables > CDC (Change Data Capture), the table list shows each source table's target table, loading mode, and status. Each Data Flow starts with the status Waiting For Migration and takes everything currently present in the table. Data Integration loads the log snapshot table only after the status changes to Streaming.
Select Tables Definitions to configure how Data Integration handles log snapshot tables and loading behavior:
- Advanced Source Definitions > Stream Configurations: shows the current log position, which updates constantly based on your database changes. Select Check Log Position to view this position — the same position used by the CDC Point in Time position feature.
- Advanced Target Definitions > Include Log Snapshot Tables: toggle this on so that Data Integration creates a log snapshot table for each updated table, containing all snapshot changes.
- Table Prefix (optional): adds a character or phrase to the beginning of the target table name, for example
ODS. - Default Loading Mode: sets how Data Integration loads the data, for example Upsert Merge.
- Merge Method: sets how Data Integration merges records, for example Switch - Merge.
- Filter Logical Key Duplication Between Files: use only when duplicates are expected in the source but not in the target table. This filters out duplications in the current source pull.
The platform records each action performed on the log snapshot table as a new entry, along with when the change occurred (in the __ts_ms column) and whether the platform deleted the record (in the __deleted column). The __deleted column is available only when a delete action occurs.
The platform treats _log tables as append-only, and in the event of a connection issue, the platform pulls data from the last successful pull to prevent any data loss. As a result, _log snapshot tables may contain duplicate records.
The original table:
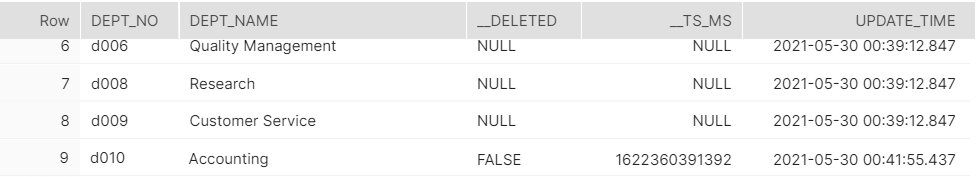
In the DBO.DEPARTMENTS table, there are two columns: DEPT_NO and DEPT_NAME. Additionally, there is a calculated expression in the target's mapping which uses current_timestamp().
Before enabling CDC (Change Data Capture) and migrating the Data Flows, the automatically included fields __deleted and __ts_ms have null values for all records.
Enable change streams extraction
After establishing a connection, go to the Source tab and do the following:
- Choose the Multi-Collection as the Data Flow mode.
- select the Change Streams as the extraction mode.
- A brief reminder appears, encouraging you to check your connection and set up your Source and Target, which will happen next. Select Got It to proceed.
- Turn the Enable Stream toggle to true at the bottom of the page.
- A new window pops up, guiding you on the following steps. Select Target.
- You will be directly sent to the Target tab, where you can choose your data target.
- Define your Target Connection, then choose a Database and a Schema to load into.
- To make sure the operation is complete, click the Enable Log toggle once more.
- To navigate to the Collections, click the Schema tab.
- You must choose a minimum of one Collection.
- To use CDC, the table must contain a key defined as the Source Column _id.
- Navigate to the Enable Stream toggle and select the number of hours you want to run the Data Flow, then click I'm Sure.
- Wait for the Initiation Log to complete its processing.
- You are all set to run your log-based Data Flow now.
- Following the completion of the Data Flow Run, return to the Schema tab and check that the Collections you selected are Streaming.
Limitations
- Time-series collections do not support Change Streams due to a limitation in MongoDB.
- There are some limitations when it comes to connecting to MongoDB (click the URI and SSH to get to their topics):
| URI | If you are using Change Streams with Atlas, leave the analytics node out of the connection URI. You can only connect to the Primary Node with MongoDB Atlas. We will be able to connect to the Analytics Node, but we cannot get any messages from it due to Atlas' implementation. |
|---|---|
| SSH | - We currently only enable SSH tunneling to a single DNS (host). This means that the SSH tunnel method does not support multiple DNSs in replicas as shown here: mymongo.shard-1.domain.com:27017, mymongo.shard-2.domain.com:27017 - If you are using Atlas with Log-Based, employ Private Endpoint to connect to several hosts. |
-
MongoDB will not send any documents that are more than 16MB in size, including all metadata in the change stream.
-
Data Integration replaces any special character with an underscore. As a result, if you wish to edit the table name, go to:
- The Schema tab
- Select a collection
- Click Table Settings
- Choose Edit to change the table name manually.
